Inference that enables continuous improvement
Dedicated inference, tuned to your workload. Close the loop between training and serving and improve your model based on production traffic.
Your inference is not a commodity
Serve. Capture production traces, including user inputs, model responses, tool outputs, and token-level log probabilities.
Improve. Use real deployment data to reduce failure modes through self-distillation and preference optimization, or to add new capabilities with reinforcement learning.
Re-deploy. Push newly trained checkpoints to your inference endpoints within minutes of training completion.
The traffic you serve today trains the model you ship tomorrow.
Deploy your checkpoint straight from a completed run.99.9% uptime, autoscaling, and low latency speculative decoding
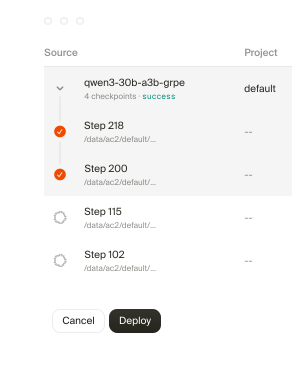
Match your workload.Each deployment is tuned to the latency and throughput requirements of your workload
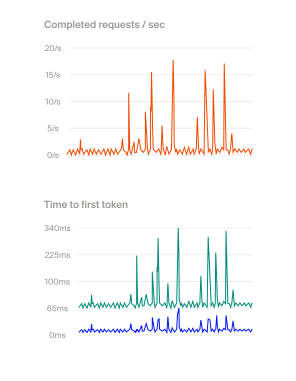
Capture production traces.Power improvement through self-distillation or convert traces to RL datapoints
Redeploy in minutes.New checkpoints deploy behind the same endpoint without changing your API, routing, access controls, or observability.
High reliability, throughput, and latency for your workload

Serving configuration.Tuned per model against a latency-vs-throughput target. Same model configured differently for interactive vs. batch.

Speculative decoding.Custom speculator trained on your traffic, one you supply, or a model-specific OSS speculator.

Autoscaling.Capacity tracks demand, with scale-up / scale-down against your designed load.

Region & Security.North America / Europe, set per deployment at design time. Single-tenant and region-lockable for enterprise residency requirements. Zero data retention supported.
Inference that adapts to your cloud strategy
BYOC or host on our cloud with the latest hardware.
Serve any model
Tuned to your traffic. High-throughput serving for async and background agents. Low-latency serving for interactive use.
Service level agreement. SLAs you provide based on product requirements. Proactive monitoring/alerting to ensure 99.9% availability.
Flexible deployment. Dedicated reserved Blackwell GPUs by default. Scale replicas as needed to meet real capacity demands. Deploy in minutes from AC2 checkpoints, Hugging Face models, or direct weight transfer.



See what open source saves you
Compare your current closed-source API spend against open-weights models.
Which model powers your workload today?
Which open-weight model would you move to?
Current monthly spend ($/mo)
What does your workload look like?
Average tokens per request
Input
Output
= 3,862,247 requests / month at this spend
Results are general estimates intended for internal discussion purposes only. Applied Compute does not guarantee that use of the Applied Compute platform will result in any particular amount of cost savings or other financial benefit. Any pricing shown here is for purposes of example only
Recommended replacement model
GLM 5.2
High-throughput open LLM for general-purpose production workloads
Cost reduction
82%
Today
$150,000/mo
Monthly savings
$123,449
Three-year savings: $10.4M
Applied Compute
$26,551/mo
List price · per 1M tokens
| Cached input | Input | Output | |
|---|---|---|---|
| GPT 5.6 Sol · Today | $0.50 | $5.00 | $30.00 |
| GLM 5.2 · Applied Compute | $0.14 | $1.40 | $4.40 |
How the savings compound
| Year 1 | Year 2 | Year 3 | |
|---|---|---|---|
| Current trajectory | $1.8M | $3.6M | $7.2M |
| On Applied Compute | $319K | $637K | $1.3M |
| Savings | $1.5M | $3M | $5.9M |
Start serving